


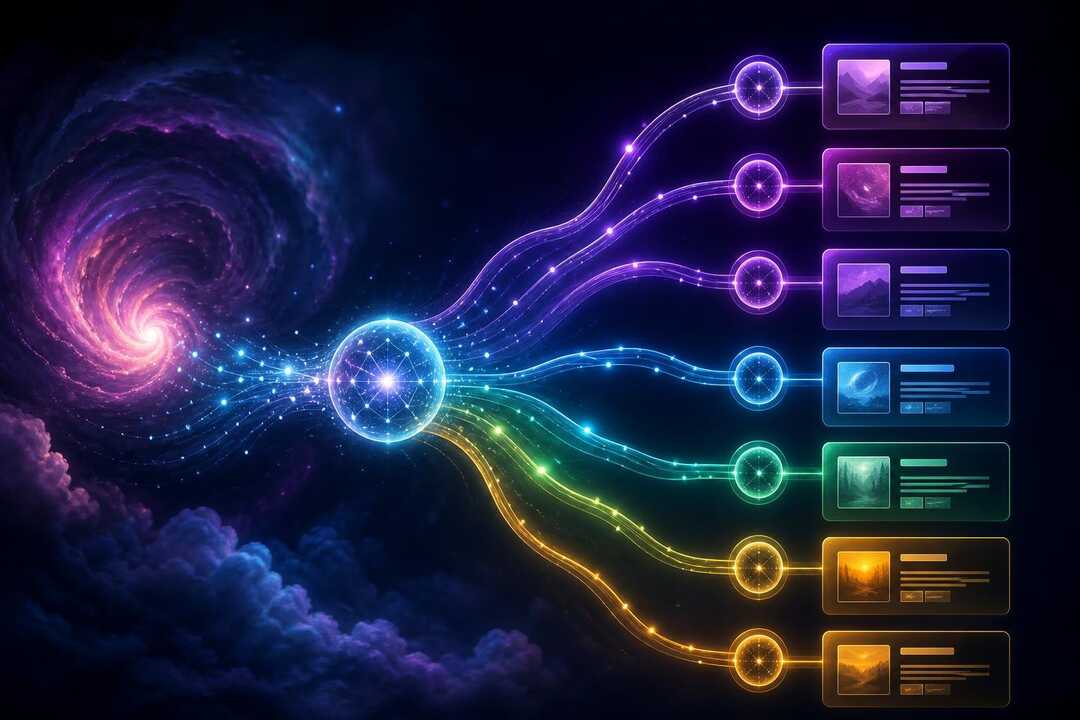
Google’s R4T-Diffusion is easiest to understand as a query-routing idea, not a blanket quality claim. In that sense, r4t diffusion query fan-out describes how one search can split into several retrieval paths.
Those paths can merge evidence later into an answer. This distinction matters because broader search may improve coverage for layered questions. It may also create more chances for overlap, drift, or weak matches.
The key issue is not fan-out alone. Each branch must stay closely tied to the original intent.
What R4T-Diffusion and Query Fan-Out Mean in Google’s AI Search Context
At a high level, r4t diffusion query fan-out suggests a shift from one request to many parallel retrieval paths. In plain terms, the system does not treat a search as a single string that returns a single ranked list.
It treats that request as a starting point, then spreads retrieval across multiple related sub-questions, records, or evidence paths before forming an answer. That framing fits a broader pattern in AI systems, where one input triggers a set of coordinated actions rather than one direct lookup.
In The Emerging AI Paper-Review Arms Race: Adversarial Co-Evolution in Scholarly Publishing, a taxonomy entry describes “production scaling” through “AI-assisted and agentic production,” listing systems that expand work across many steps and tools.
Another entry describes “record ingress and persistence,” which matters because once many records enter the system, they can keep shaping later outputs. In a search context, that means fan-out is not just about speed or scale.
It changes where relevance is decided. Instead of judging one query against one index pass, the system may judge which branches to open, which sources to pull forward, and which pieces to merge back into a final response.
The tradeoff is clear. More branches can improve coverage for layered questions, but they can also widen the path for weak matches, duplicated evidence, or drift from the original intent. That is the key lens for reading the framework.
How Set-Valued Retrieval Changes the Path From One Query to Many
Set-valued retrieval changes the job before any final answer is written. Instead of finding one best match, the system must assemble a working set. The path from one query to many is therefore more than expansion.
It involves filtering, merging, and grounding. Each added branch can widen coverage for layered questions. It can also introduce overlap, weak evidence, or side topics. A useful parallel appears in Robot Learning from Human Videos: A Survey.
The review says one hour of human data can yield about 1400 demonstrations, versus 135 from one hour of robot data. The gain is scale, but scale alone is not the endpoint. The same survey notes that mixed dataset compositions can improve diversity.
It also notes that latent-action methods may absorb camera motion or background change instead of controllable actions. In plain terms, more inputs create more possible signal and more possible noise. That is why r4t diffusion query fan-out matters at the retrieval stage itself.
Once a system opens several evidence paths, quality depends on how well it keeps each branch tied to the original task. Precision no longer lives only in ranking the last list. It also lives in deciding which branches deserve to exist.
The system must decide which records belong together and which patterns are distractions. For readers, this shifts attention from raw breadth to controlled breadth.
What Evidence Supports the Framework and What It Still Cannot Show
A framework can support a narrower claim than a result claim. It can show how a system is organized. It can show which decisions it makes. It can show where those decisions enter the retrieval path. For r4t diffusion query fan-out, the clearest support is structural, not promotional.
The framework can indicate that one search may split into several retrieval branches. Those branches may be merged later. Relevance may be judged more than once across different stages of the process. That matters because architecture shapes failure modes.
If branching happens early, errors can spread early too. A weak sub-query may pull in off-topic material. Overlapping branches may repeat the same evidence under different wording. The framework therefore supports a realistic interpretation.
Broader coverage is plausible, but branch creation and control must both be strong. What it still cannot show is equally important. A framework diagram or method description does not prove better answer quality.
It does not prove better factual grounding or satisfaction across all query types. It also cannot show whether gains come from fan-out itself. They may come from later ranking or other unseen parts of the system.
The practical takeaway is simple. Read the framework as evidence of mechanism and design intent, not proof of universal search improvement.
Where Query Fan-Out Helps Results and Where It Can Add Noise or Miss Intent
Branching helps most when a question has several valid angles to gather first. In that setting, r4t diffusion query fan-out can improve coverage. Retrieval can follow parallel paths instead of forcing one narrow reading too soon.
That is a sensible design pattern, not a guaranteed win. A survey article archived by PubMed Central comes from the Athena Research and Innovation Center. It describes multi-branch architectures, such as Inception networks, which process features at multiple scales at once.
These architectures can improve performance on complex tasks like semantic segmentation. The comparison with search is limited, but still useful. Multiple branches can capture different parts of a layered query that one pass might miss.
Yet the same structure can also add noise. More branches create more chances for overlap, weak matches, or side issues that only seem related. If the original query is vague, the system may spread that vagueness across several retrieval paths instead of resolving it.
Breadth can then work against intent. Coverage rises, but precision may fall. That tradeoff matters more than the fan-out label itself. Query branching is most useful when the system can open diverse paths while keeping them tied to one clear information need.
If that control is weak, extra branches may look comprehensive while making the final result less exact.
In plain terms, R4T-Diffusion describes a branching retrieval design, not a proven quality upgrade. Its strongest support is structural: one query can split into several evidence paths and merge them later.
That setup may help with layered questions by widening coverage early. The main limit matters just as much. More branches can repeat evidence, drift from the original intent, or pull in weak matches. Therefore, r4t diffusion query fan-out is best understood as a useful search framework.
Its value depends on strong control of each branch, rather than proof of universally better answers.