Google’s added mention of Retry-After matters because it makes crawl guidance clearer. It shows how temporary server strain can be communicated to Googlebot during short overload windows. That makes the change operational, not a new SEO control.
Table of Contents
Retry-After can slow repeat requests for a time, especially with a 503 response. However, it does not choose rankings, indexing, or long-term crawl behavior. The key question is where that boundary lies and when a short-term throttle points to a deeper technical problem instead.
What Changed in Google’s Crawl Rate Guidance on Retry-After
If crawl rate guidance now calls out Retry-After more directly, the real change is about clarity, not a new SEO lever. It frames temporary server strain as something a site can signal with a standard HTTP response pattern, instead of leaving crawlers to infer intent from a generic error alone.
That matters because it narrows the purpose of the header. Retry-After is a short-term coordination signal, not a way to choose what gets indexed or to set a permanent crawl pace. In practice, the update points teams toward cleaner communication during overload windows and away from using server responses as broad ranking or indexing controls.
The useful takeaway is to treat the change as operational guidance for temporary throttling, then validate implementation carefully.
When Retry-After Helps—and What It Does Not Control
Retry-After helps most when the problem is temporary and capacity based. In that narrow case, it can reduce wasted requests and give infrastructure breathing room. That makes it an operations signal, not a content management tool.
It does not choose which URLs deserve attention first. It also does not decide whether a page is indexed, kept indexed, or ranked well. Those outcomes depend on broader crawl, quality, and serving signals.
The key boundary is time. If the underlying issue is persistent, a polite delay message will not fix it. It may only postpone the same friction. For teams weighing crawl rate retry-after, the practical decision is simple: use it to smooth short bursts of strain, not to steer long-term search behavior.
How Googlebot Uses 503 and Retry-After During Server Throttling
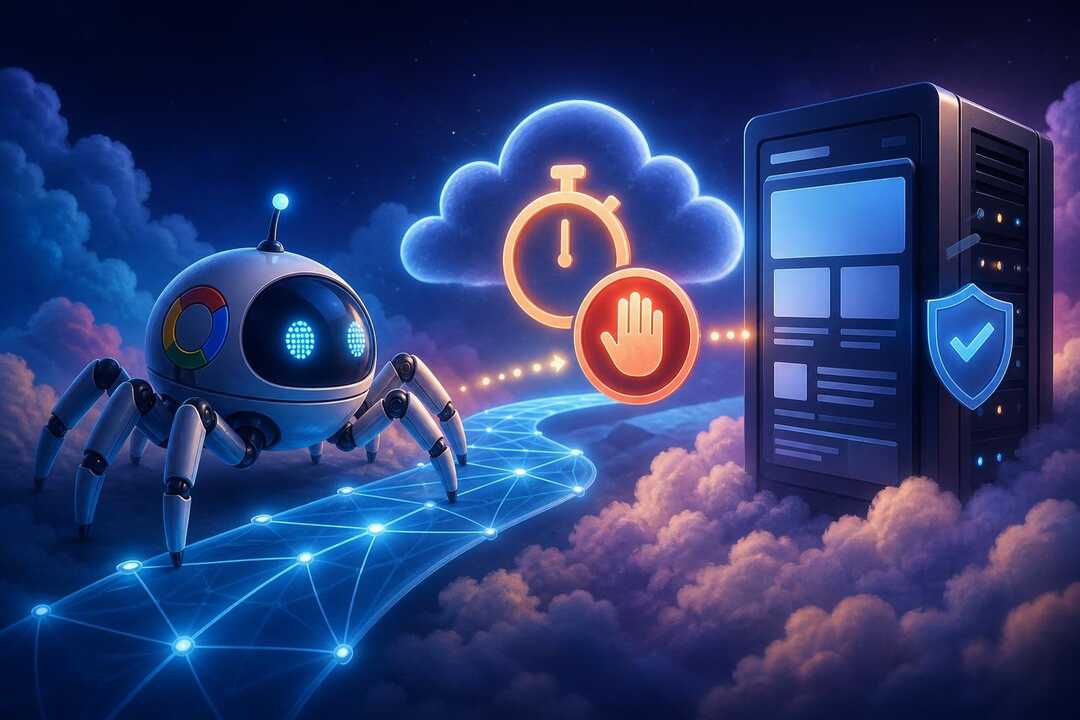
During server throttling, the key signal is the combination, not either part alone. A 503 status tells Googlebot the problem is temporary, so the issue looks like availability, not a permanent removal.
Retry-After adds a timing hint that asks the crawler to come back later instead of retrying right away. In practice, that makes crawl rate retry-after a load-management signal for short strain windows.
It is not a request to recrawl preferred URLs first, and it is not a lasting cap on crawl activity. The important limit is that this pairing communicates temporary pressure, not strategy. If the server keeps failing after the delay passes, the header does not solve the underlying problem.
Use it to buy recovery time, not to shape search outcomes.
Which Retry-After Format to Use and How Long to Set It
The practical goal is consistency, not cleverness. For crawl rate retry-after, choose the format the stack can return correctly every time. A precise delay helps only when the response itself is reliable.
Timing should match a short recovery window, not a broad guess about future load. In most cases, set a brief pause that covers the actual strain period. Then let normal crawling resume. A long delay can send the wrong operational signal when the issue clears quickly.
A very short delay may invite repeated retries before capacity returns. The useful rule is simple. Choose the cleanest valid format. Set the shortest realistic delay. Base both choices on real server recovery time for that temporary strain, rather than SEO preference alone.
How to Configure Retry-After on Common Web Servers and CDNs
Configuration matters less than product choice and more than control point. The safest setup is to return Retry-After at the layer that already serves the temporary 503 response, whether that is the origin server, reverse proxy, load balancer, or CDN edge.
That keeps the status code and delay aligned during short capacity events. In practice, teams should confirm four things: the rule triggers only for temporary overload, the header is added to the same response path, cached error pages do not persist the signal longer than intended, and monitoring can verify the header appears when expected.
For crawl rate retry-after, consistency is the main goal. If a stack cannot apply the header cleanly, a simpler temporary-throttling path is usually safer than a brittle partial rollout.
How to Tell Temporary Throttling From Deeper Crawl or Indexing Problems
The clearest dividing line is whether the stress is brief and system-level or ongoing and page-level. Temporary throttling usually appears during short capacity spikes. It then fades once serving stabilizes.
Deeper crawl or indexing problems tend to persist across checks. They can affect discovery, refresh, or visibility after the overload window ends. That means diagnosis should start with duration and scope, not with the header alone.
If crawl rate retry-after is present, pages can still fail to load cleanly. They may return inconsistent status codes or remain hard for crawlers to fetch later. In that case, the issue is likely bigger than controlled slowdown.
In practice, Retry-After can explain a pause. It cannot explain a lasting inability to serve pages reliably or surface them consistently.
Risks of Misusing Retry-After for Maintenance, Blocks, or SEO Goals
That boundary matters most when teams start treating Retry-After as a broader control. During planned maintenance, it can fit a brief service interruption. It becomes risky when maintenance stretches on, repeats often, or masks unresolved availability problems.
The same misuse appears when the header is treated like a soft block. It may delay crawling for a time, but it does not replace clear access, status, or indexing controls. SEO misuse is another trap. A crawl rate retry-after response is not a signal for prioritizing preferred pages or suppressing weaker ones.
Used that way, it can create confusion, hide operational faults, and slow recovery data. The safer decision is to reserve it for short, real server strain and handle longer goals with the correct technical tools.
Rather than adding a new SEO lever, Google’s crawl rate Retry-After guidance clarifies how to signal short-term server strain. The header matters when a site returns a temporary 503 and needs brief recovery time.
In this narrow role, it can reduce repeated requests and support cleaner throttling. Its limits matter just as much. It does not control indexing, rankings, URL priority, or long-term crawl pace. The practical takeaway is simple: use it for real, temporary overload.
Treat persistent crawling problems as a deeper serving or technical issue.